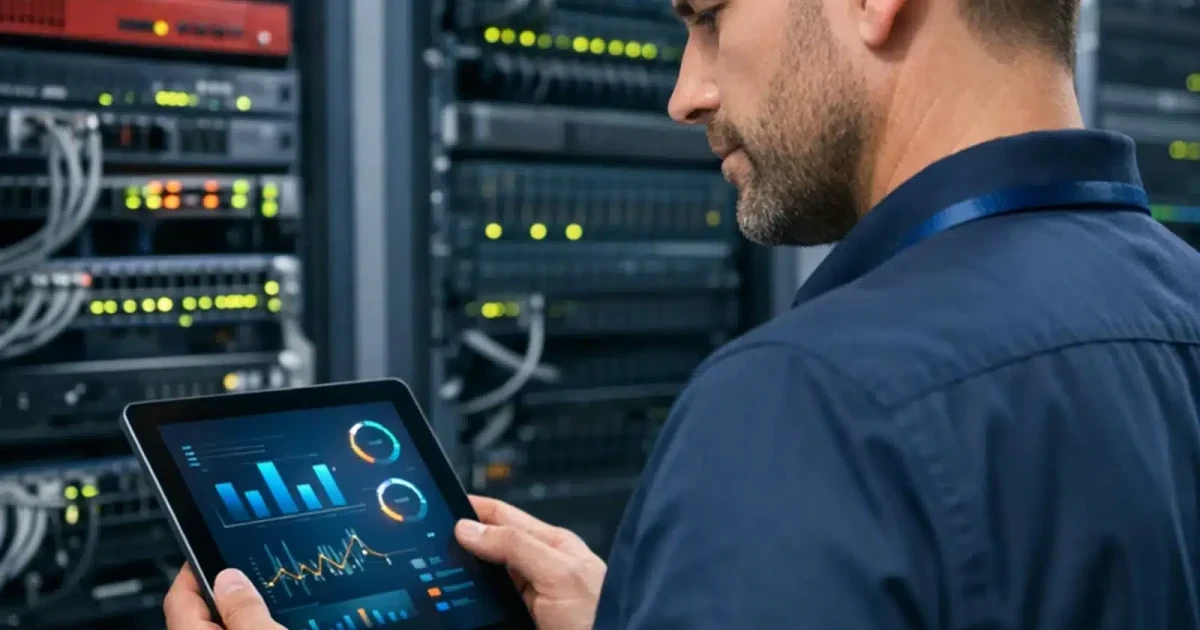
Network monitoring should answer two questions at any hour: what business service is at risk, and what action should happen next. A flood of device alarms without ownership does not protect email, cloud applications, phones, point-of-sale systems, cameras, remote access, or customer operations. Useful monitoring connects equipment and telemetry to locations, dependencies, severity, response steps, and the people affected.
Continuous coverage begins with a current inventory and a service map. Internet circuits, firewalls, switches, wireless access points, servers, virtualization, storage, cloud connections, DNS, certificates, VPN, voice systems, power protection, and environmental sensors may all contribute to one employee-facing service. Monitor availability, performance, errors, capacity, configuration, security, and telemetry freshness, then distinguish an incident from planned maintenance or a failed monitoring path.
ALLMSP provides 24/7 network monitoring and response for businesses in Lawrenceville, Suwanee, Gwinnett County, Metro Atlanta, and across Georgia. Our in-house team discovers infrastructure, builds useful checks, responds to alerts, communicates with stakeholders, troubleshoots remotely or on site, coordinates carriers and product support, and verifies that work has recovered.
Connect every alert to a service, owner, and response
- Map dependencies: Relate circuits, power, firewalls, switching, wireless, servers, cloud services, DNS, voice, and critical applications.
- Measure health: Collect reachability, latency, loss, interfaces, errors, utilization, hardware, services, logs, configuration, and security signals.
- Define severity: Use affected service, location, users, redundancy, data, security, duration, and recovery requirement.
- Route response: Assign acknowledgment, diagnosis, escalation, communication, vendor coordination, dispatch, and incident ownership.
- Control noise: Suppress maintenance, group dependent alarms, detect stale telemetry, tune thresholds, and remove unactionable notifications.
- Prove recovery: Validate connectivity, applications, phones, wireless, security, monitoring, and user work before closure.
Map the network around the services employees and customers use
Create a monitored inventory for every site and cloud connection. Record device identity, model, serial, software or firmware, management address, physical location, rack and power source, interfaces, uplinks, carrier, circuit identifier, public address, support contract, configuration backup, owner, and lifecycle status. Include wireless controllers and access points, virtual networks, tunnels, DNS, certificates, authentication dependencies, voice gateways, cameras, access control, printers, storage, and remote-user services when they affect business availability.
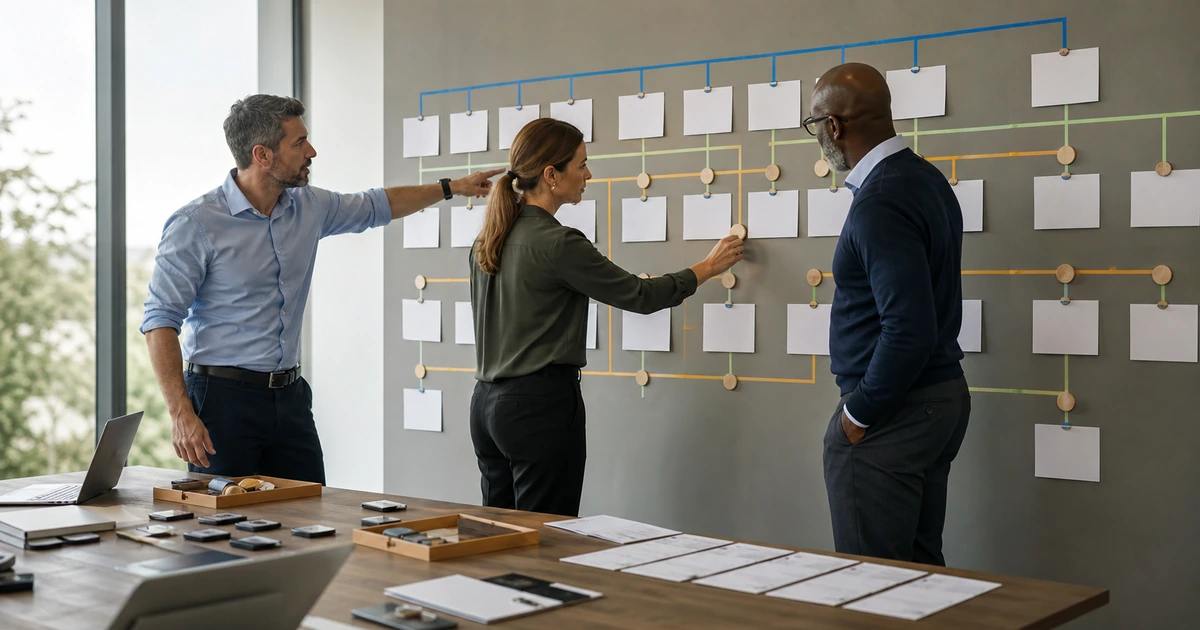
Build dependency views from the outside inward. A public application may rely on DNS, a certificate, internet routing, firewall policy, load balancing, cloud compute, database, identity, and monitoring collectors. A branch may depend on power, carrier equipment, firewall, switch uplink, wireless, DHCP, DNS, VPN, and SaaS access. Mark redundancy and shared failure points. This allows one circuit failure to create one actionable incident instead of dozens of disconnected alarms from everything behind it.
- Site record: Document address, hours, contacts, circuits, public addresses, power, equipment, access, and dispatch details.
- Device context: Track identity, model, version, interfaces, location, support, configuration, credentials route, and lifecycle.
- Service map: Show the technical chain behind internet, cloud applications, voice, wireless, printing, cameras, and remote access.
- Failure domain: Identify shared power, carrier, switch, firewall, authentication, DNS, cloud, and configuration dependencies.
- Ownership path: Name technical responder, business contact, carrier, product support, property access, and escalation authority.
Monitoring becomes understandable when a responder can move from one alarm to the affected service and every dependency in its path.
Design checks and alert severity around business consequence
Use multiple signal types. Availability checks confirm reachability or service response. Performance measures reveal delay, loss, jitter, congestion, interface errors, retransmission, resource pressure, wireless quality, and capacity. Health checks detect fan, temperature, power supply, disk, process, certificate, tunnel, and failover conditions. Configuration and security monitoring identifies unauthorized changes, exposed services, authentication failures, suspicious traffic, and disabled logging. A heartbeat or last-seen measure is essential because silence may mean the monitoring path itself failed.
Define severity with business context. A complete outage at an operating site, failure of both redundant paths, security detection, or loss of a revenue-critical service may require immediate response. Degraded guest wireless after hours may warrant investigation without waking every contact. Set persistence and confirmation rules so transient loss does not create false incidents, but do not average away short failures that interrupt voice or transactions. Each alert should include the asset, service, location, symptom, duration, dependencies, recent change, runbook, owner, and next escalation time.
- Availability: Check circuit, route, tunnel, device, service, application, DNS, certificate, and external customer path.
- Performance: Measure latency, loss, jitter, interface errors, utilization, wireless quality, storage, memory, and processing pressure.
- Hardware health: Watch temperature, fan, power, battery, disk, transceiver, port, controller, failover, and environmental state.
- Security signal: Monitor configuration changes, authentication anomalies, exposed services, suspicious traffic, and missing logs.
- Alert package: Provide service impact, context, evidence, runbook, owner, acknowledgment deadline, and escalation clock.
An actionable alert describes a consequence and a response, not merely a threshold that happened to be crossed.
Operate acknowledgment, investigation, communication, and closure
Create a documented 24/7 response path. Confirm who receives each severity, expected acknowledgment, after-hours authority, customer communication, remote-access requirements, carrier or vendor escalation, on-site dispatch, and incident leadership. Verify the alert before making disruptive changes. Check monitoring freshness, dependency failures, maintenance records, recent changes, configuration state, logs, path tests, and user reports. Preserve evidence when security or repeated instability may require deeper investigation.
During an incident, communicate what is affected, who is affected, when it began, what remains available, the current action, and when the next update will arrive. Restore the most important business function first, then resolve the underlying cause. Test from the user and external perspectives before closure. Confirm monitoring is healthy, queued alerts clear for the right reason, temporary changes are removed or documented, vendor cases have owners, and the incident record contains timeline, cause, resolution, validation, and prevention work.
- Acknowledge: Confirm receipt, severity, affected service, assigned responder, next action, and escalation deadline.
- Investigate: Review topology, telemetry freshness, dependencies, path tests, logs, configuration, maintenance, and recent change.
- Communicate: State impact, available alternatives, action, owner, next update time, and recovery expectations.
- Restore: Use failover, configuration correction, carrier escalation, replacement, alternate access, or controlled recovery.
- Close: Validate real work, clear temporary measures, document evidence, assign prevention, and confirm monitoring coverage.
Round-the-clock monitoring earns trust when every meaningful signal reaches an accountable response and a verified business outcome.
24/7 network monitoring and response from ALLMSP
ALLMSP can discover network assets, document service dependencies, configure supported monitoring platforms, establish baselines, build severity rules, and create escalation procedures. We cover infrastructure, connectivity, wireless, cloud paths, certificates, hardware health, and related security signals.
When an alert fires, our in-house team can investigate, communicate, coordinate carriers and manufacturers, perform remote remediation, dispatch when needed, and validate service restoration. Ongoing reviews reduce noise and turn incident history into concrete reliability improvements.
- Observe: Monitor service availability, performance, hardware, configuration, security, and telemetry freshness.
- Respond: Acknowledge, diagnose, communicate, escalate, restore, and preserve evidence around the clock.
- Improve: Tune checks, close coverage gaps, correct recurring causes, and report service outcomes.
Authoritative guidance for continuous monitoring
Use formal monitoring guidance to shape strategy and evidence, then adapt the checks and response path to the organization’s own services and risk.
- NIST information security continuous monitoring. Covers monitoring strategy, visibility into assets and threats, control effectiveness, and timely risk response.
- CISA Cross-Sector Cybersecurity Performance Goals. Provides prioritized practices and measurable security outcomes for organizations of different sizes.
- CISA network monitoring findings. Highlights insufficient host and network visibility and recommends establishing and tuning normal traffic baselines.
- ALLMSP managed IT services. Connects monitoring with help desk, device care, patching, backup, documentation, and accountable response.
24/7 network monitoring FAQs
Cover circuits, firewalls, switches, wireless, servers, cloud paths, DNS, certificates, VPN, voice, power, hardware health, security signals, and telemetry freshness.
What should 24/7 network monitoring cover?
No. It can reveal developing problems, shorten detection and response, support failover, and provide evidence for prevention, but it cannot remove every failure.
Does monitoring prevent every outage?
It identifies the affected service and location, includes useful evidence and dependencies, names an owner, links response steps, and starts an escalation clock.
What makes a network alert actionable?
How are false alarms reduced?
Use baselines, persistence, confirmation checks, dependency grouping, maintenance suppression, threshold tuning, and recurring review of alerts that produced no action.
Should internet circuits be monitored from outside the office?
Yes. External checks can reveal public reachability and customer-path problems that an internal collector may not see.
How is wireless performance monitored?
Review controller and access-point health, channel use, interference, client experience, authentication, roaming, capacity, uplinks, and site-specific coverage evidence.
What happens when an after-hours alert occurs?
The assigned responder validates severity, investigates dependencies, communicates based on impact, escalates as defined, restores service, and records the outcome.
How is recovery verified?
Test the service from relevant internal and external paths, confirm user workflows, review security and monitoring state, and clear temporary changes.
Can ALLMSP monitor and repair the network in house?
Yes. ALLMSP handles monitoring design, alert response, troubleshooting, carrier coordination, hardware support, documentation, and verification with its own team.
Where does ALLMSP provide network monitoring?
For businesses in Lawrenceville and Suwanee, ALLMSP can operate network monitoring across Gwinnett County, Metro Atlanta, and additional Georgia locations.