A disaster recovery plan should tell authorized people how to restore a minimum usable business service when normal technology or facilities are unavailable. It is more than a list of backup products. The plan connects business priorities with people, decision authority, identity, networks, applications, data, devices, providers, communications, alternate work methods, security, validation, and the return to normal operations.
The most practical way to build the plan is service by service. Start with outcomes such as accepting orders, treating patients, producing designs, answering customers, running payroll, or shipping products. Then identify the technology and people each outcome requires. This approach exposes dependencies that a server inventory misses, including DNS, multifactor authentication, certificates, internet circuits, SaaS access, printers, phones, integrations, and employees who know how the workflow operates.
ALLMSP develops and maintains disaster recovery plans in house for organizations in Lawrenceville, Suwanee, Gwinnett County, Metro Atlanta, and across Georgia. We translate business requirements into recovery architecture, protected runbooks, testable acceptance criteria, and a maintenance schedule tied to real technology changes.
Build the plan in six connected steps
- Name critical services: Define the business outcomes, users, customers, deadlines, minimum functions, and impact that determine recovery priority.
- Set recovery targets: Approve maximum interruption, recovery time, acceptable data loss, minimum capacity, declaration threshold, and service order.
- Map dependencies: Trace people, identity, network, facilities, devices, platforms, data, applications, integrations, providers, keys, and communications.
- Choose strategies: Select restore, rebuild, replication, alternate connectivity, spare devices, cloud capacity, manual work, or standby service per dependency.
- Write runbooks: Give every action an owner, prerequisites, exact steps, expected time, validation, fallback, evidence, and escalation path.
- Test and maintain: Exercise the plan, correct failures, update it after change, train alternates, and retain current protected copies.
Complete a business impact analysis and approve recovery targets
List the services the organization delivers and the internal operations that enable them. For each service, record the owner, users, customers, operating hours, peak periods, locations, transaction volume, deadlines, legal or contractual obligations, safety concerns, financial impact, customer impact, and manual alternative. Estimate what happens after one hour, one business day, several days, and a longer outage. This creates an evidence-based priority instead of assuming the most expensive server is the most important system.
Define the maximum tolerable interruption, recovery time objective, recovery point objective, and minimum operating state for each service. Recovery time should include decisions, access, containment, dependencies, restoration, security checks, business validation, communication, and user restart. Recovery point identifies how much recent data might be lost. Minimum operation states the users, locations, transactions, capacity, and features required before the service is useful. Give each target a business approver and note any assumption that still needs testing.
Set declaration and priority authority. Identify who decides that an incident has become a disaster, who may contain systems, approve emergency spending, contact providers, change service order, communicate with customers, accept recovered operation, and begin failback. Name alternates for every critical role. Record notification thresholds and a status cadence. NIST contingency planning guidance connects business impact, recovery strategies, plan development, testing, training, and maintenance, which is why targets and ownership belong in the plan before technical steps.
- Service record: Capture outcome, owner, users, customers, hours, locations, transactions, deadlines, obligations, and impact over time.
- Recovery time: Approve the complete elapsed target from disruption through validated minimum operation.
- Recovery point: State the acceptable data-loss window and the business consequence of missing recent transactions.
- Minimum operation: Define required users, functions, data, capacity, devices, locations, security, and manual alternatives.
- Authority: Name primary and alternate decision makers for declaration, containment, priority, spending, communication, acceptance, and failback.
The business impact section is usable when leaders have approved priorities, measurable targets, minimum operating conditions, and decision authority for each critical service.
Map dependencies and select a recovery method for each one
Write executable runbooks and maintain the plan through change
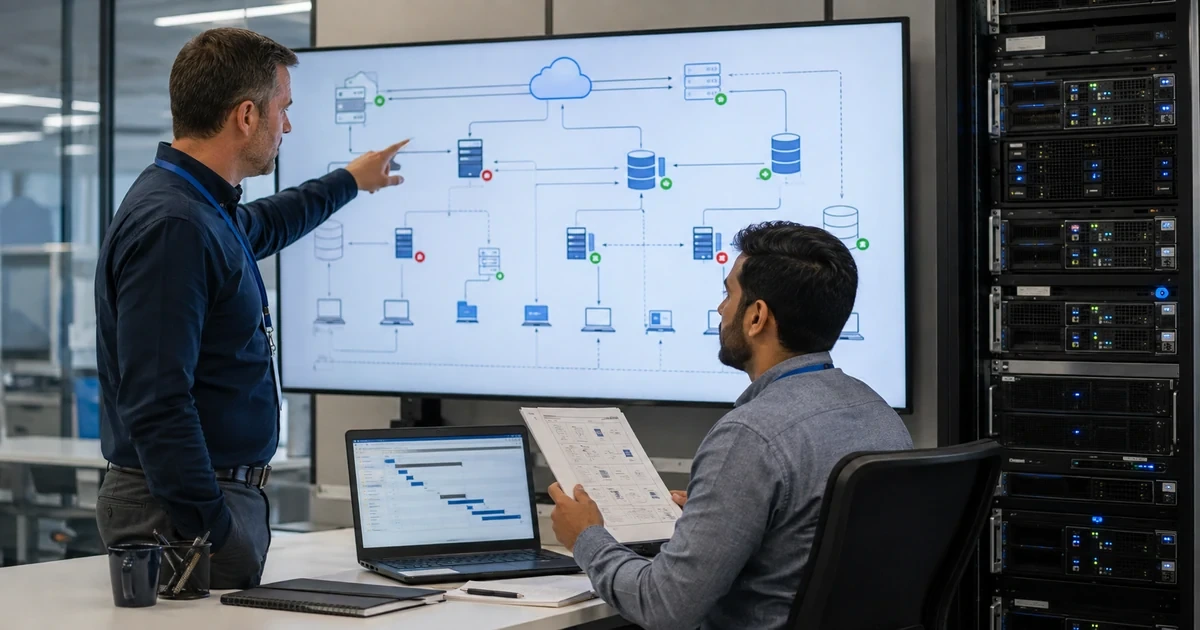
Draw the service from the employee or customer action backward through every requirement. Include identity providers, privileged accounts, multifactor methods, DNS, domain registration, internet and carrier paths, firewalls, VPN, switching, Wi-Fi, servers, virtualization, cloud resources, storage, databases, files, SaaS platforms, applications, APIs, certificates, keys, licenses, endpoints, phones, printers, scanners, facilities, electricity, cooling, documentation, providers, and trained people. Mark shared dependencies because one identity or network failure can stop many services at once.
Choose a recovery method that can meet the approved target. Backup and rebuild may fit a service that can wait. Replication, preconfigured cloud capacity, alternate internet, spare devices, or a warm standby may be needed for a shorter objective. A manual process can preserve a limited business function for a short time if forms, authority, data capture, reconciliation, and employee training are ready. Cloud applications still need plans for account control, configuration, exports, integrations, endpoints, communication, and provider escalation.
Design for trustworthy recovery after a cyber event. Protect independent administrative identities, authentication methods, encryption keys, backup consoles, infrastructure definitions, software sources, licenses, monitoring, and clean devices. Keep protected copies of the plan and contacts outside the systems whose failure the plan addresses. CISA recommends offline or otherwise protected backups and regular restoration testing. Record how the team will select a clean point, contain compromised systems, validate restored assets, and prevent reinfection before reconnection.
- Dependency map: Connect people, identity, DNS, networks, platforms, data, applications, keys, devices, facilities, providers, and communications.
- Failure domain: Identify shared accounts, buildings, power, carriers, routes, clouds, regions, administrators, suppliers, and control planes.
- Recovery method: Assign restore, rebuild, replication, standby, alternate service, spare equipment, manual work, or a combined method.
- Capacity: Confirm compute, storage, bandwidth, licenses, devices, power, facilities, staff, and transaction throughput for minimum operation.
- Trusted access: Protect emergency identities, keys, consoles, scripts, software, documentation, communication paths, and clean devices.
The architecture section is credible when every required dependency has a recovery method, owner, target, protected access path, and known capacity.
Disaster recovery planning and implementation from ALLMSP
Create one coordination guide for the incident and a runbook for each recovery tier or service. Include trigger, authority, contacts, prerequisites, containment, clean-environment requirements, dependency order, precise actions, expected duration, evidence, validation, fallback, communication, and escalation. Link to scripts and diagrams without embedding reusable secrets. Give each step a role and an alternate. Store controlled copies where they remain reachable during an identity, cloud, network, or site failure.
Define acceptance tests in business language. A recovered accounting service might require an authorized employee to sign in, open the current company file, view recent transactions, enter a controlled test item, produce a report, verify printing or export, and confirm audit history. A recovered customer service may require telephony, email, customer records, routing, and a complete request. Include security validation, performance, minimum capacity, communication, and cleanup. Plan failback, including how transactions created during recovery return to the primary environment.
Maintain the plan as part of normal change management. Review it after tests, incidents, new applications, cloud migrations, network changes, office moves, provider changes, staffing changes, acquisitions, major upgrades, and revised business priorities. Verify contacts and emergency access on a shorter schedule than the full exercise. Track corrections by owner and retest them. READY Business and NIST both frame recovery as a continuing planning process, not a document that can remain untouched until an emergency.
- Coordination guide: Define declaration, command, status, priorities, communications, providers, evidence, safety, and closure.
- Service runbook: List prerequisites, dependency order, actions, owners, expected time, validation, fallback, and escalation.
- Acceptance test: Specify user, device, transaction, data, output, integration, security, capacity, and approval evidence.
- Failback: Plan trusted primary state, data synchronization, conflict resolution, user transition, monitoring, approval, and rollback.
- Maintenance: Assign review frequency and triggers for contacts, access, architecture, priorities, runbooks, tests, and corrective actions.
The finished plan should be short enough to navigate under pressure, detailed enough for trained alternates to execute, and current enough to match the real environment.
Official disaster recovery planning references
ALLMSP can lead business impact analysis, dependency mapping, architecture, backup and cloud design, emergency-access protection, runbook development, communication planning, exercises, and maintenance with its in-house team.
Our scope can connect servers, cloud services, Microsoft 365, Google Workspace, identity, networks, security, endpoints, applications, data, phones, monitoring, and employee procedures. Every recovery statement is tied to an owner, an observable test, and retained evidence.
- Define: Identify critical services, impacts, targets, minimum operation, decision authority, and acceptance criteria.
- Design: Map dependencies and build recovery methods, protected access, capacity, runbooks, and communications.
- Maintain: Exercise the plan, implement corrections, train alternates, and update it as technology and operations change.
Disaster recovery planning FAQs
Use these frameworks to organize the plan, then tailor priorities, targets, dependencies, runbooks, and acceptance tests to the organization’s actual operations.
- NIST contingency planning guide. Provides a lifecycle for impact analysis, recovery strategies, plan development, testing, training, and maintenance.
- NIST cybersecurity event recovery guide. Connects recovery planning, playbooks, communications, metrics, and improvement after cyber events.
- CISA StopRansomware guide. Covers protected backups, restoration testing, incident preparation, containment, and recovery.
- Ready Business emergency and recovery planning. Connects business continuity with technology, data, equipment, applications, and provider planning.
- Azure disaster recovery architecture guidance. Explains roles, targets, failure domains, runbooks, communications, exercises, and failback.
What should a small business disaster recovery plan contain?
Include critical services, business impact, recovery targets, decision authority, contacts, dependencies, recovery methods, protected access, runbooks, communications, acceptance tests, failback, exercise records, and maintenance responsibilities.
What is a recovery time objective?
It is the target elapsed time for restoring a resource or service. A useful service target includes decisions, access, dependencies, security checks, business validation, communication, and user restart.
What is a recovery point objective?
It is the maximum acceptable point in time to which data may be restored. It describes potential data loss and helps determine backup or replication frequency and design.
How should recovery priorities be chosen?
What dependencies are commonly missed?
Use safety, legal and contractual obligations, customer impact, revenue, operational deadlines, data loss, manual alternatives, dependencies, outage duration, and approved business impact rather than technology cost alone.
Does cloud software eliminate disaster recovery planning?
Identity, DNS, multifactor methods, certificates, keys, internet routes, providers, licenses, integrations, printers, phones, clean devices, facilities, documentation, and people with specialized knowledge are often missed.
Where should the disaster recovery plan be stored?
No. The business still needs plans for identity, administrators, configuration, data recovery, exports, integrations, endpoints, connectivity, communication, provider escalation, and complete workflow validation.
When should the recovery plan be updated?
Keep controlled, protected copies in locations that remain accessible during the failures the plan addresses. Do not place the only copy behind the identity, network, cloud, or building access that may be unavailable.
Can ALLMSP build and maintain the plan in house?
Update it after tests, incidents, new or retired systems, cloud and network changes, office moves, provider changes, staffing changes, acquisitions, major upgrades, and revised business priorities.
Where does ALLMSP provide disaster recovery planning?
Yes. ALLMSP can assess, design, implement, document, exercise, monitor, and improve disaster recovery across infrastructure, cloud, backup, identity, network, security, applications, endpoints, and communications with its in-house team.
ALLMSP supports organizations in Lawrenceville, Suwanee, Gwinnett County, Metro Atlanta, and throughout Georgia, including businesses with hybrid systems, cloud platforms, and remote workers.