A retail or restaurant technology problem is rarely expensive because of the repair alone. The real cost appears in slower lines, abandoned orders, manual reconciliation, manager distraction, inconsistent customer experiences, overtime, and repeated vendor calls. Optimization should therefore begin with business interruption evidence rather than a generic list of upgrades.
The strongest review connects tickets, monitoring, point-of-sale records, network data, device inventory, employee observations, vendor incidents, and financial exceptions. It distinguishes a failed device from a weak cable, an overloaded wireless channel from poor roaming, a processor delay from local packet loss, and a training gap from a configuration problem. That evidence supports a targeted correction instead of replacing whatever component is easiest to blame.
ALLMSP improves retail and restaurant technology through its in-house service team for Lawrenceville, Suwanee, Gwinnett County, Metro Atlanta, and organizations across Georgia. We trace disruptions through the complete workflow, correct root causes, coordinate product vendors, document the environment, and verify that changes reduce customer and employee impact.
Turn recurring disruptions into an ordered improvement program
- Quantify interruption: Measure lost transactions, delayed orders, employee workarounds, manager time, reconciliation, refunds, and customer impact.
- Reconcile inventory: Match active devices, network records, software versions, vendors, locations, owners, warranties, spares, and retirement status.
- Trace representative cases: Follow symptoms through device, cable, switch, wireless, internet, cloud, account, integration, support, and resolution evidence.
- Establish baselines: Record healthy transaction, print, roaming, latency, loss, throughput, device, backup, and application behavior by location.
- Prioritize corrections: Rank safety, payment, security, revenue, customer, recovery, frequency, effort, dependency, and lifecycle risk.
- Verify improvement: Test the corrected workflow under realistic demand and monitor recurrence through an agreed observation period.
Build a fact base from incidents, devices, networks, and business impact
Collect a representative period of help desk tickets, manager notes, point-of-sale incidents, processor notices, internet outages, wireless events, device alerts, application status, backups, security findings, change records, and vendor cases. Normalize the time zone, location, device name, affected workflow, start, restoration, business impact, apparent cause, confirmed cause, workaround, and resolution. Separate planned maintenance, user mistakes, duplicates, tests, and unrelated provider outages so the analysis does not inflate or hide a pattern.
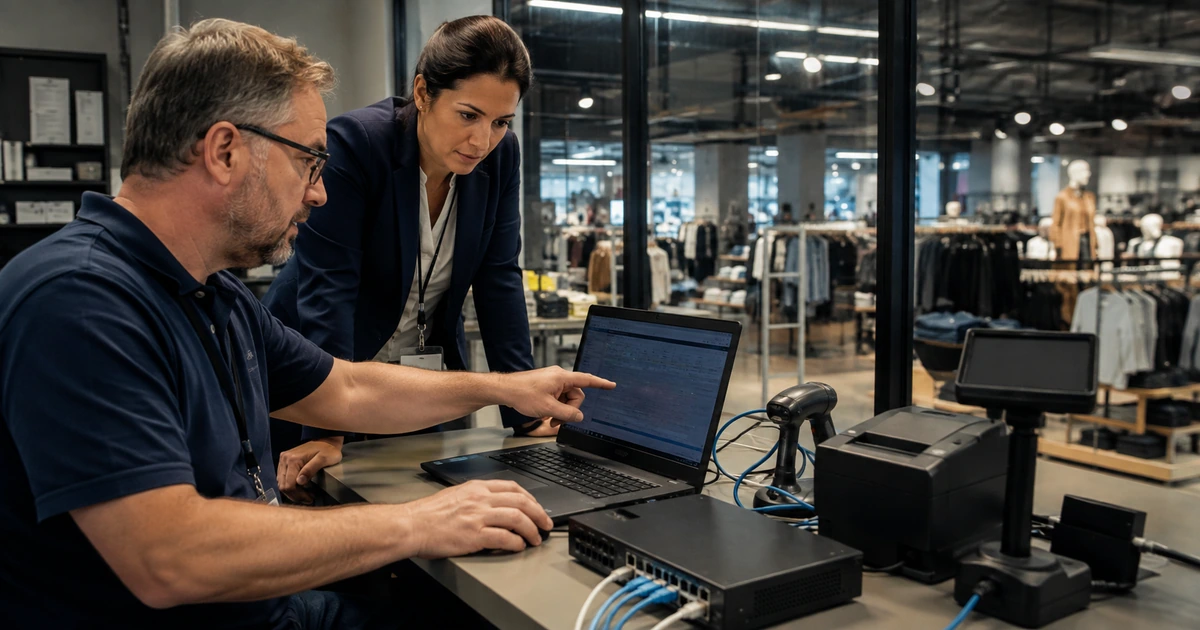
Reconcile the physical and logical inventory. Walk each location and compare terminals, readers, printers, scanners, tablets, displays, access points, switches, firewalls, UPS units, circuits, cameras, office computers, and spare equipment with management records. Identify unlabeled cables, consumer switches, unsupported devices, duplicate addresses, stale agents, shared passwords, abandoned vendor hardware, heat, dust, overloaded power, missing surge protection, and equipment placed where staff or customers can disconnect it. Photograph and label the finished state for support use.
Translate technical events into operating impact. Record whether a problem stopped sales, affected one lane, delayed kitchen production, interrupted online orders, created a payment exception, increased wait time, required manual entry, prevented a refund, changed inventory accuracy, or consumed manager attention. A five-minute outage during opening prep is not equal to five minutes during a peak line. Use frequency, timing, reach, revenue exposure, security impact, recovery effort, and customer consequence to rank work.
- Incident sample: Record location, time, workflow, symptom, device, scope, impact, evidence, workaround, confirmed cause, change, and recurrence.
- Physical inspection: Check labels, cables, ports, power, heat, dust, placement, tampering, damage, spares, and environmental risk.
- Logical inventory: Reconcile hostnames, addresses, accounts, agents, versions, licenses, groups, monitoring, backups, and vendor ownership.
- Business measure: Capture transactions, orders, wait, manual work, refunds, reconciliation, customer complaints, and manager time.
- Priority score: Combine payment, safety, security, revenue, frequency, duration, reach, recovery, lifecycle, and implementation effort.
A shared fact base prevents every vendor from declaring its own component healthy while the complete customer workflow remains unreliable.
Correct point-of-sale, wireless, printing, device, and connectivity causes
For point-of-sale incidents, trace a transaction from employee input through terminal, local application, payment reader, network path, processor, integration, receipt, inventory, and reporting. Compare working and failing lanes. Check supported versions, device health, time synchronization, local storage, security agents, peripheral drivers, cables, power, port errors, DNS, latency, packet loss, and vendor status. Preserve logs before restarting equipment. A reboot may restore service while erasing the evidence needed to prevent the next failure.
For wireless issues, measure the location and device at the time of failure. Review signal, interference, channel use, client count, roaming, retries, latency, packet loss, power levels, access-point placement, firmware, and authentication. Compare handheld ordering devices, scanners, tablets, and laptops because they do not have identical radios or roaming behavior. Correct coverage holes, excessive overlap, poor channel plans, overloaded access points, sticky clients, weak uplinks, and devices connected to the wrong network. Retest during peak occupancy.
Treat printers, scanners, tablets, and displays as managed production endpoints. Standardize supported models, firmware, drivers, addresses, power, consumables, cleaning, spare parts, and replacement procedures. Keep a small verified spare pool for components whose failure stops service. Remove uncontrolled desktop switches, extension cords, adapters, and personal chargers from production paths. Apply changes in a controlled window, document the prior state, define rollback, and test the whole workflow rather than the changed device alone.
- Transaction trace: Follow user, terminal, reader, network, processor, integration, output, inventory, settlement, and reporting evidence.
- Wireless trace: Compare client, location, signal, channel, retries, roaming, latency, loss, authentication, uplink, and application result.
- Peripheral standard: Define approved models, firmware, drivers, network settings, supplies, cleaning, spares, swap steps, and disposal.
- Change package: Record reason, owner, affected locations, configuration, backup, risk, schedule, test, rollback, communication, and result.
- Vendor evidence: Provide exact timestamps, identifiers, logs, transaction references, network tests, versions, screenshots of interfaces, and business impact.
Root-cause work follows a failed transaction or task across system boundaries instead of repeatedly treating the last visible symptom.
Improve monitoring, failover, maintenance, and operational learning
Build monitoring around service outcomes. Circuit and device uptime matter, but they do not prove that an employee can complete an order. Combine infrastructure health with synthetic or controlled workflow checks where practical. Alert on sustained packet loss, circuit failure, access-point faults, port errors, terminal or agent inactivity, storage pressure, backup failures, certificate expiration, security events, and vendor incidents. Route each alert to an owner with location context, criticality, diagnostic steps, and escalation. Review noisy alerts until every notification is actionable.
Test continuity instead of assuming it. Confirm how terminals behave when the primary circuit fails, how quickly backup connectivity activates, which cloud and payment paths use it, whether bandwidth is sufficient, and how service returns to normal. Check UPS runtime and graceful shutdown for network equipment. Verify configuration backups and protected copies of essential business data. Exercise the fallback with managers and record transaction reconciliation, not just a successful ping. PCI DSS responsibility remains relevant during degraded operation.
Create a recurring improvement review. Group incidents by confirmed cause, location, model, version, circuit, provider, time, change, and workflow. Assign permanent work for patterns such as weak cabling, printer wear, unsupported systems, capacity, inconsistent configuration, shared accounts, incomplete training, or vendor handoff failures. Track baseline, correction, cost, result, side effects, and recurrence. Update runbooks and retire workarounds that should no longer be used.
- Outcome monitoring: Connect infrastructure signals to payment, ordering, printing, inventory, online sales, and reporting availability.
- Useful alert: Include location, service, severity, start, evidence, probable scope, first action, owner, and escalation.
- Continuity test: Verify failover timing, usable workflows, security, capacity, power runtime, employee steps, restoration, and reconciliation.
- Maintenance rhythm: Schedule updates, inspections, cleaning, battery checks, spare validation, account reviews, and lifecycle replacements.
- Problem record: Document pattern, confirmed cause, affected locations, owner, permanent change, test period, result, and follow-up.
A reliable operation learns from recurring evidence and spends improvement time where it measurably reduces interruptions.
Evidence-based retail technology optimization from ALLMSP
ALLMSP can collect incidents, reconcile inventory, inspect locations, analyze point-of-sale and network paths, survey wireless service, standardize devices, correct configuration, improve monitoring, test failover, coordinate vendors, and document permanent fixes. The team that performs the audit can implement and support the resulting changes in house.
We help retailers and restaurants in Lawrenceville, Suwanee, Gwinnett County, Metro Atlanta, and across Georgia reduce recurring technology disruption at one site or throughout a multi-location environment.
- Investigate: Trace incidents, inventory, network evidence, device conditions, workflows, vendor cases, and operating impact.
- Correct: Repair infrastructure, standardize endpoints, tune wireless service, secure access, improve monitoring, and remove weak workarounds.
- Sustain: Test failover, manage changes, review patterns, maintain documentation, report results, and plan replacements.
Official retail technology security references
Use current system and processor documentation alongside contractual, acquiring-bank, insurance, regulatory, and payment-card requirements.
- PCI Data Security Standard. Describes the technical and operational baseline for protecting payment account data.
- PCI SSC merchant security process. Organizes payment security around networks, configurations, data, access, monitoring, testing, and policy.
- PCI SSC payment terminal guidance. Explains why terminal type and configuration affect applicable controls and assessment work.
- NIST Cybersecurity Framework. Supports risk-based governance and continuous improvement across technology and business operations.
Retail and restaurant IT optimization FAQs
Where should a retail IT optimization review begin?
Begin with business interruptions, representative tickets, monitoring, device inventory, network evidence, vendor incidents, employee observations, and the complete affected workflow.
Why do point-of-sale problems keep returning after a reboot?
A restart may clear the symptom while leaving weak cabling, failing storage, software defects, network loss, unsupported versions, power issues, or integration errors unchanged.
How can a business prove that Wi-Fi is the cause?
Capture device, location, time, signal, channel, retries, roaming, latency, packet loss, authentication, access-point load, uplink health, and application behavior during the event.
Should every location use the same hardware?
Standardization usually improves support and spares, but validate models against each location’s workflow, environment, connectivity, capacity, payment, and lifecycle requirements.
What should be kept as spare equipment?
Prioritize verified devices and components whose failure stops sales or fulfillment, considering replacement time, configuration effort, cost, compatibility, and storage conditions.
How is internet failover tested safely?
Use a planned window, controlled interruption, approved transaction tests, capacity checks, security verification, employee procedures, restoration, and reconciliation evidence.
Which retail technology alerts are useful?
Useful alerts identify the location, affected service, severity, duration, evidence, likely scope, first action, responsible owner, and escalation route.
How can vendor support cases be resolved faster?
Provide exact times, location, device and transaction identifiers, versions, logs, network tests, prior changes, reproducible steps, business impact, and an accountable contact.
Can ALLMSP fix problems across several technology vendors?
Yes. ALLMSP traces the complete workflow, works directly with product vendors, implements network and device corrections, verifies results, and maintains support in house.
Where does ALLMSP optimize restaurant and retail IT?
ALLMSP serves Lawrenceville, Suwanee, Gwinnett County, Metro Atlanta, and businesses throughout Georgia with remote and onsite support.