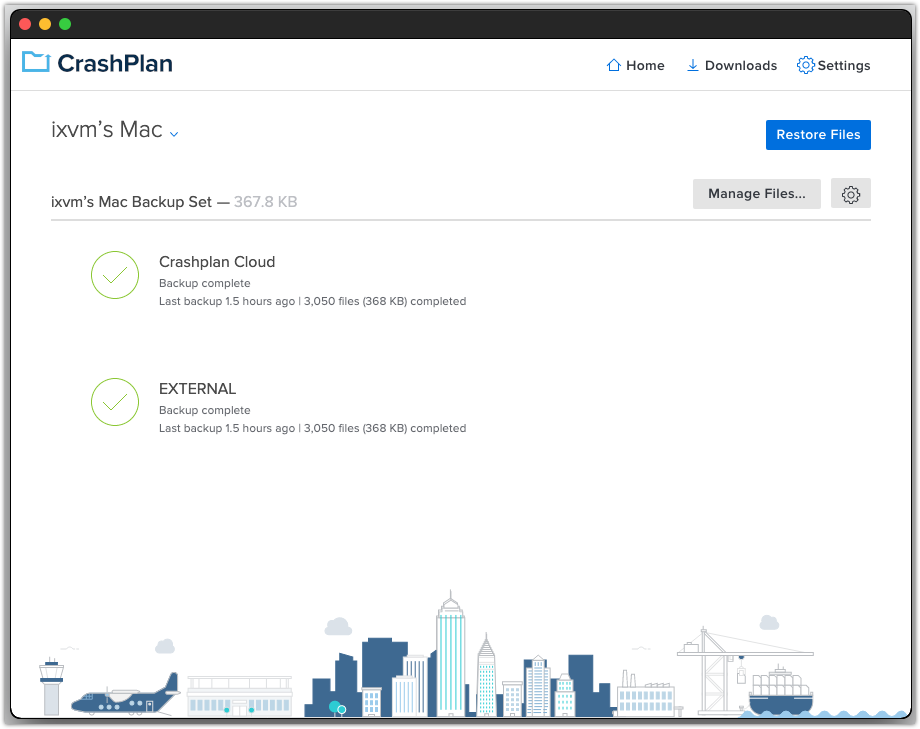
CrashPlan’s published app example shows two destinations marked Backup complete for a small sample selection. That status describes the selected files and destination; it does not prove that every business path was selected or that a recovery test passed.[8] View full-size image
A CrashPlan installer can report success while a laptop is registered to the wrong person, selecting almost no useful data or never completing its first backup. Before expanding a rollout, join three records: the expected endpoint inventory, the actual CrashPlan device and destination, and an approved sample restore. An unexplained gap in that chain is an exception to resolve, not a protected endpoint to count.
Use this guide to design registration, test a representative pilot and reconcile production coverage. Enterprise deployment policies and reporting must be checked against the actual product entitlement. The worked example below shows how to withhold acceptance from a device that looks green but has the wrong selection; it is an illustrative support record, not a client result.
This playbook treats rollout as an evidence-driven service transition. It distinguishes CrashPlan for Enterprise capabilities from plan-dependent options, keeps user and device details restricted, and gives operations teams concrete gates for design, pilot, production expansion, coverage reconciliation, and restore ownership.
Our in-house team delivers CrashPlan deployment and configuration for businesses around Lawrenceville, Suwanee, Gwinnett County, Metro Atlanta, and the rest of Georgia, while coordinating the applications, identities, devices, data, security controls, and employees affected by the work.
Key decisions at a glance
- Design CrashPlan organizations, authentication, provisioning, and backup defaults before distributing an installer because one deployment policy belongs to one organization and child organizations do not inherit it.
- For silent registration, prove that the destination is configured for Use, that usernames resolve to current CrashPlan email addresses, and that every detection script returns the intended home directory and organization.
- Treat SCCM, Jamf Pro, or another endpoint tool as a delivery mechanism, it does not validate registration, selected data, destination connection, backup progress, or restore readiness.
- Pilot Windows, macOS, and Linux cohorts against the current CrashPlan requirements, network path, Full Disk Access needs, exclusions, performance settings, and representative business data.
- Reconcile console devices and stored data against an authoritative endpoint inventory, then investigate every missing, stale, tiny, offline, or incomplete archive with a named owner and deadline.
Design Organizations, Identity, Destinations, and Backup Defaults First
Start with a restricted service inventory. Record each endpoint’s business owner, operating system, supported version, architecture, device role, primary user, user-home layout, storage volumes, network pattern, proxy requirement, mobility, Full Disk Access state on macOS, authoritative asset identifier, maintenance window, and retirement date. Keep full usernames, email addresses, hostnames, serials, directory paths, organization registration keys, deployment tokens, and console URLs out of public documentation. Compare each cohort with CrashPlan’s current hardware and software requirements before assigning it to a wave. Do not reuse an old compatibility worksheet after an operating-system or CrashPlan app release.
Build the CrashPlan organization hierarchy before adding users and devices. CrashPlan recommends creating organizations first because settings and administration scope follow that hierarchy. Decide which cohorts genuinely need different authentication, backup selection, retention, bandwidth, reporting, visibility, or security controls. Avoid mirroring every department if the result is a deep tree that nobody can explain. A deployment policy belongs to one organization, an organization has one policy, and child organizations do not inherit a parent’s deployment policy. Record the intended registration organization for every endpoint group and the administrator who owns its policy.
Select provisioning and authentication as separate decisions. User Directory Sync, SCIM, or manual administration may be available according to the current product plan and identity design. Authentication can be local or SSO at the organization level, while local exceptions need explicit governance. Current CrashPlan cloud usernames must be email addresses. Define the authoritative mapping from an endpoint login to that email, identify shared or service devices that cannot be mapped safely, and choose manual registration whenever precision cannot be proven. Configure device backup defaults before silent installation. Verify the intended user data selection, exclusions, frequency, retention, performance, network rules, alerts, and destination.
CrashPlan’s deployment guide explicitly requires at least one destination listed as Use for the silent-deployment prerequisite and says Auto-start alone is not acceptable in that check. Capture the exact console evidence rather than treating a similar label as equivalent. Default selections focus on user files. Application databases, virtual machines, system files, redirected folders, external drives and multi-user devices need separate analysis; an endpoint file backup is not proof of application-consistent or full-system recovery. Prefer supported application dumps for live databases instead of assuming an open database becomes a consistent endpoint backup.
Test inclusions and exclusions across the supported platforms in scope, and remember that global or cloud exclusions can remove data from archives as well as future collection. Treat plan-dependent API, directory, local-destination and advanced administration features as unavailable until the actual entitlement is confirmed.
CrashPlan recommends designing organizations before enrollment.[1] Its deployment guide distinguishes registration and destination prerequisites from installer delivery.[2] Backup-policy design and exclusions require separate review because selected paths can affect recoverability.[6][7] Use the console settings reference to check the actual security and restore defaults.[12]
Build Deployment Policies and Detection Scripts That Fail Safely
Create one controlled deployment policy for each registration organization that needs it. Record the policy name, organization, authentication method, automatic-registration decision, operating systems, username and home-directory script owner, proxy state, desktop-launch behavior, token rotation owner, installer source, signing or package-verification method, and planned retirement. CrashPlan indicates that creating or using these policies requires Customer Cloud Admin access, use that highly privileged role only for the bounded setup action and move routine monitoring to narrower roles. Never paste installation properties, deployment tokens, registration keys, console addresses, proxy credentials, or real script output into public tickets.
Detection scripts are identity controls, not installation convenience. For the CrashPlan cloud, the script must output an email-address username and the correct home directory, an optional organization registration key can direct the endpoint to a particular organization. Test each script under ordinary user, administrator, remote-worker, renamed-account, multiple-profile, service-account, and noninteractive installation conditions. Normalize case only if the identity source does. Reject empty, local-only, truncated, shared, or guessed usernames. CrashPlan warns that a mismatched silent SSO deployment can create a user with no usable password who cannot restore data or access the console.
If the script cannot map precisely, switch that cohort to manual registration. Handle local silent registration carefully as well: generated passwords are hidden, so console access later requires an administrator to set a new password. Keep the authentication method stable after policy creation because changing the registration organization’s authentication can invalidate the design. Package delivery through Microsoft Configuration Manager, Intune, Jamf Pro, another MDM, RMM, or software distribution system must preserve vendor origin and deployment properties. Use the current CrashPlan installer for the correct platform, approved install commands, least-privilege distribution rights, and a package hash or signing check.
Define what happens if the endpoint cannot reach the CrashPlan cloud, because policy retrieval retries and registration can continue later. A stale deployment token or improperly scoped package should fail visibly and open a ticket instead of creating an unmanaged shadow install. For macOS, coordinate privacy controls and Full Disk Access with the current management workflow, for Windows or Linux, test service context, home-directory detection, proxy handling, and reboot behavior. Generate a new policy token if unauthorized exposure is suspected, understanding that not-yet-installed packages using the previous token will fail and must be replaced.
Investigate registrations during the exposure window rather than assuming rotation removes devices that already registered.
The deployment-policy reference defines registration organization, detection-script output and token rotation behavior; use it for the exact policy and authentication method in scope.[3]
Pilot Backup Behavior, Not Just Installer Exit Codes
Create a test organization and a representative pilot that includes each supported operating system, device role, network condition, identity path, user-home variation, and storage pattern. Include a Mac requiring Full Disk Access, a remote Windows device behind the approved proxy or direct path, a Linux desktop if the current plan and operating-system lifecycle support it, an external drive where business data legitimately lives, a user with redirected folders and an ordinary laptop with a realistic working set. CrashPlan’s current requirements require a graphical desktop environment; do not quietly include a headless server in that pilot.
Keep test data synthetic or sanitized. Define pass criteria before deployment: installer authenticity, service start, policy retrieval, exact email registration, correct organization, correct device owner, expected destination, nonzero selected data, approved exclusions, allowed network route, acceptable CPU and bandwidth behavior, alert delivery, completed initial backup, and a successful sample restore. Review the CrashPlan console and endpoint evidence together. The organization device count should match the pilot manifest, stored data should become greater than zero, and the selected bytes should be credible for the user’s profile. A tiny archive can indicate a detection or file-selection problem even when the device is online.
Confirm last connection, last backup activity, completion percentage, destination, operating system, application version, and alert state. On selected endpoints, inspect the current CrashPlan service log for deployment-policy retrieval, script output, authentication, and backup activity, but sanitize it before evidence leaves the restricted ticket. Do not copy real tokens, server addresses, email addresses, home paths, GUIDs, or file names into a broad channel. Validate settings behavior, including the difference between saving defaults for future devices and pushing or locking a change to existing devices. A pilot setting can look correct at the organization level while an already-enrolled endpoint retains an older value.
Confirm intended inheritance and lock behavior with both a device that should accept user changes and one that must not. Measure user impact during initial backup and normal incremental operation. Test battery thresholds, active and away CPU, bandwidth windows, excluded interfaces, proxy failover, sleep, network changes, and large-file behavior. Include a representative restore to a controlled target, then verify contents and permissions. Stop the rollout for identity mismatches, inaccessible data, unintended exclusions, destination errors, excessive resource use, persistent warning states, restore failure, or documentation that an operator cannot follow without the original engineer.
Check the current app requirements, including the graphical-desktop requirement,[5] then distinguish saved defaults from pushed or locked endpoint settings.[4] The app status example describes a selected backup, not proof that the intended business files were selected or restored.[8]
Worked pilot gate: two installed laptops, one accepted
Illustrative support record using synthetic devices and data. Assume the approved selection is a 12 GB working folder plus a small known test file; the figures are acceptance inputs for this example, not recommended sizes for every user.
| Evidence | PILOT-A | PILOT-B | Acceptance decision |
|---|---|---|---|
| Installer and identity | Installer succeeded; expected email and organization | Installer succeeded; expected email and organization | Both pass delivery and registration only. |
| Selection and destination | 12 GB expected folder selected at the approved destination | Only a 400 KB empty-profile sample selected; status says complete | Hold B. Compare detection-script home output and selection with the intended folder; a complete tiny selection is still a coverage gap. |
| Recovery control | Known file restored to a clean folder; contents and permissions checked | Required business sample is absent from the archive | A passes this sample; B remains an open exception, without marking the rollout fully covered. |
| Retest and ownership | Retain the evidence and include in the next ring | Named engineer corrects the mapping, completes backup and repeats the same restore | Expand only after each in-scope asset is accepted or has an explicitly approved exception. |
Reconcile Production Coverage and Transfer It to Operations
Expand in bounded rings by site, operating system, identity pattern, and business criticality. Preserve the pilot controls, publish support messaging, stagger initial uploads to protect shared links, and keep a rollback path for the software package without deactivating archives. A failed install and a failed backup are different incidents, route them to owners who can inspect the endpoint, identity, console, destination, network, and policy layers. Monitor both deployment-system results and CrashPlan health during every wave. Reconcile CrashPlan devices against the authoritative endpoint inventory instead of reporting only the console’s green population.
Classify devices as expected and healthy, expected but absent, installed but unregistered, registered to the wrong user or organization, online without credible selected data, actively backing up, complete, warning, critical, stale, blocked, deauthorized, deactivated, duplicate, or retired. Investigate endpoints with abnormally small archives, old app versions, long gaps since connection or backup activity, unresolved Full Disk Access state, excluded business paths, or selected data that never reaches a destination. CrashPlan’s Device Status report can export useful fields, but its results are limited to the first 1,000 returned. Refine searches into non-overlapping cohorts, record each query and reconcile the combined device identifiers to the expected inventory.
Do not treat one full report as complete coverage. CrashPlan identifies the DeviceBackupReport API as an alternative for larger results; API access still requires the appropriate product plan and role. Protect exports because they contain user, device, organization, network, and archive context. Define service levels for missing endpoints, no-backup alerts, first-completion time, stale connections, failed destinations, and restore-test exceptions. Set owners for organization design, identity provisioning, SSO, deployment policies, installer lifecycle, backup defaults, exclusions, retention, encryption-key policy, alert recipients, device health, license review, restores, offboarding, and vendor escalation. Choose coverage-reconciliation and representative-restore intervals from the organization’s recovery objectives and change rate.
Monthly reconciliation and quarterly restore sampling are example schedules, not a CrashPlan requirement; shorten the interval where the risk or contract requires it. Treat device retirement carefully. Uninstalling software, blocking access, deauthorizing a device, and deactivating an archive have different effects. Production cleanup must not destroy the only recoverable copy. Verify retention, legal-hold obligations, and plan-specific cold-storage behavior before any destructive action. Close the rollout only when every in-scope asset has an explicit state and every exception has an owner, compensating control, deadline, and tested recovery path. The durable result is a repeatable mapping from asset inventory to CrashPlan user, organization, device, selected data, destination, backup health, alert ownership, and restore evidence.
Use documented console device issues to triage exceptions,[9] and observe the Device Status report’s 1,000-result limit when assembling coverage evidence.[10] Use the Users reference for the actual account and export fields.[11] The API usage guide separately requires an entitled product plan, supported credentials and appropriate resource permissions.[13]
Before granting rollout administrators broader rights, use the CrashPlan role and policy review to separate monitoring from restore and destructive powers. Then run the controlled restore and replacement tests against the actual pilot archive.
Official product documentation and ALLMSP resources
Frequently Asked Questions
Does a successful CrashPlan app installation prove the endpoint is protected?
No. Check the expected device against its actual user, organization, destination and intended file selection, then complete a controlled restore. A device that backs up an empty profile can legitimately show completion while missing the business folder. Keep it as an exception until the mapping and selection are corrected and the same recovery control passes.
Why must CrashPlan cloud usernames be email addresses during deployment?
Current CrashPlan cloud registration expects email-address usernames. A detection script that returns a local login or guesses the mapping can create an unusable account that cannot restore or sign in. Test an authoritative mapping for every cohort, and choose manual registration whenever an exact match cannot be guaranteed.
Can child CrashPlan organizations inherit a deployment policy?
No. CrashPlan documents one deployment policy per organization, and child organizations do not inherit a parent’s policy. Record the intended registration organization for each cohort, create or maintain its policy deliberately, and do not assume a parent policy will silently cover a newly created child organization.
Is a CrashPlan destination set to Auto-start enough for silent deployment?
Not for the prerequisite described in CrashPlan’s current deployment guide. That workflow directs administrators to verify at least one destination is listed and set to Use, and explicitly says Auto-start is not acceptable for that check. Capture the actual destination state before deploying silent-registration packages.
Should CrashPlan use SSO or local authentication for endpoint rollout?
Choose according to the organization’s identity design, recovery needs, and current plan, then keep the deployment policy aligned with that method. SSO requires a precise email mapping to the identity provider. Local silent registration creates hidden generated passwords, so later user access requires an administrator-managed password process.
What should a CrashPlan pilot test include?
Include the supported desktop platforms, identity mappings, network paths and data locations that the rollout will actually use. CrashPlan requires a graphical desktop environment, so a headless server is not an ordinary supported pilot case. For each cohort, verify registration, intended selected files, destination, completed backup, alerts and a sample restore; test resource impact during both initial and incremental backup.
How should SCCM or Jamf Pro be used with CrashPlan?
Use the endpoint-management platform to deliver the current signed installer and the exact protected deployment properties. Keep tokens and registration data restricted, capture deterministic install results, and then validate registration and backup state in CrashPlan. The deployment tool cannot by itself prove that files reached a destination.
How can administrators verify CrashPlan coverage after rollout?
Start with the authoritative endpoint inventory, then join actual CrashPlan device identifiers, owners, organizations and destinations to it. Compare selected bytes, archive size, completion, last activity and alerts. The Device Status report returns only the first 1,000 results: use documented cohort queries and deduplicate the combined export, or an entitled API workflow, before claiming the inventory is reconciled.
Are CrashPlan API reports available in every plan?
No assumption should be made. CrashPlan documents that API access depends on the product plan and the calling account’s role. Verify entitlement first, prefer read-only reporting resources for health checks, use token authentication, restrict exported data, and retain a console-based reconciliation process when API access is unavailable.
When is a CrashPlan deployment complete?
Close the rollout when every expected asset is accepted or has an approved, owned exception with a deadline and compensating recovery plan. Keep evidence of intended selection and a representative restore, not only installer success or a green status. Operations must accept the alert queue, installer and policy lifecycle, restore procedure and offboarding responsibilities before the deployment team hands over.
Sources
- CrashPlan: Administrator's guide to getting started with CrashPlan ↩
- CrashPlan: Deploy CrashPlan apps ↩
- CrashPlan: Deployment policies reference ↩
- CrashPlan: Configure device backup settings ↩
- CrashPlan: Hardware and software requirements ↩
- CrashPlan: Considerations for defining backup policies ↩
- CrashPlan: Include and exclude files for backup ↩
- CrashPlan: Check the status of your backup ↩
- CrashPlan: Monitoring device health in the console ↩
- CrashPlan: Device Status report reference ↩
- CrashPlan: Users reference ↩
- CrashPlan: CrashPlan console settings ↩
- CrashPlan: API syntax and usage prerequisites ↩